News
The Mini PC That Runs Llama 3 Locally: Beelink GTR9 Pro 395 Review
Jul
The Mini PC That Runs Llama 3 Locally: Beelink GTR9 Pro 395 Review
The Problem Nobody Talks About
You’ve read the headlines. “AI will transform your business.” “LLMs are the new electricity.” Then you check the API pricing. $30 per million tokens for GPT-4. $15 for Claude. At scale, that’s a mortgage payment every month.
And there’s the other problem: your customer data, financial records, and proprietary code are leaving your building every time you hit “generate.”
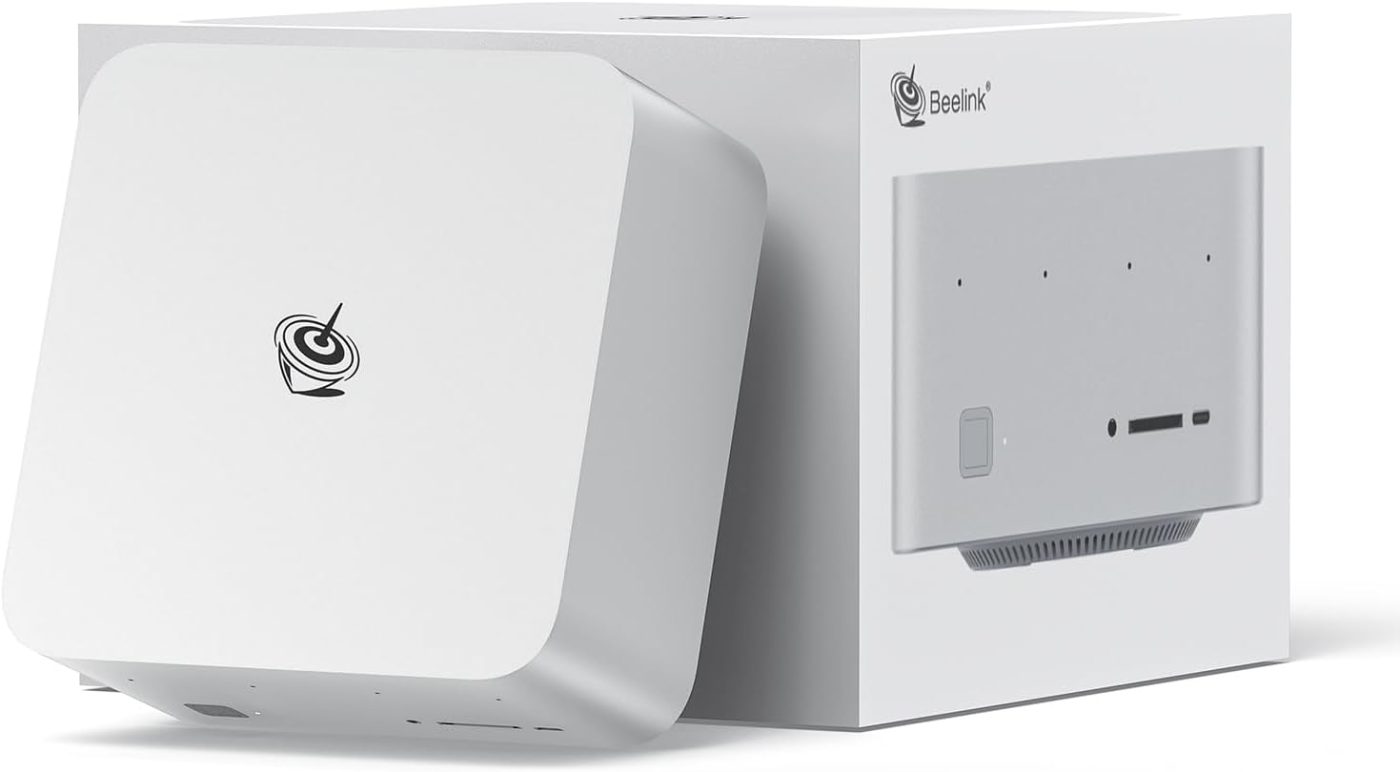
That’s why the Beelink GTR9 Pro 395 caught my attention. It’s a mini PC the size of a sandwich that delivers 126 TOPS of AI compute. In plain English: it can run Llama 3 70B at 4-bit quantization entirely on your desk. No cloud. No per-token fees. Your data never leaves the room.
The Hardware in Plain English
The Brain: AMD Ryzen AI Max+ 395. This isn’t a laptop chip crammed into a tiny case. It’s a 16-core, 32-thread Zen 5 CPU with a built-in XDNA 2 NPU rated at 50 TOPS and a Radeon 8060S GPU with 76 TOPS. Combined: 126 TOPS. That’s more AI horsepower than an RTX 3090 while drawing a fraction of the power.
Memory: 128GB LPDDR5X at 8000 MHz. Unified memory. This is the killer feature. The CPU, NPU, and GPU all share the same 128GB pool. No copying data between system RAM and VRAM. For LLMs, this means you can fit models that would choke a 24GB GPU.
Storage: 2TB PCIe 4.0 NVMe. Fast enough for model loading. Add a second drive via the empty M.2 slot if you’re building a model library.
Connectivity: Dual 10Gbps Ethernet (yes, two), USB4, WiFi 7, Bluetooth 5.4. You can cluster these. Two GTR9s linked over 10GbE give you 256GB unified memory and 252 TOPS — enough for Llama 3 405B at 4-bit.
Size: 4.9 x 4.9 x 1.8 inches. VESA mountable. It disappears behind a monitor.
What This Means for Your Business
### Scenario 1: The 20-Person Law Firm
Problem: Associates spend 15 hours/week reviewing contracts. Cloud AI works but client confidentiality agreements forbid uploading documents.
Solution: GTR9 Pro runs Llama 3 70B locally. Fine-tune on your clause library. Associates highlight a clause → instant redline suggestions. Zero data leaves the office. Break-even: 3 weeks vs. API costs.
### Scenario 2: The Software Agency
Problem: Junior devs need code review. Senior devs are bottlenecks. GitHub Copilot is $19/seat/month but sends code to Microsoft.
Solution: Run CodeLlama 34B or DeepSeek Coder 33B locally. Every dev gets a “senior reviewer” that knows your codebase, your patterns, your private repos. $4,349 one-time vs. $4,560/year for 20 seats.
### Scenario 3: The Marketing Team
Problem: Content creation at scale. Blog posts, email sequences, ad copy. ChatGPT Plus hits rate limits. Team plan is $600/month.
Solution: Run Nemotron 3 Ultra or Qwen 2.5 72B locally. Unlimited generation. Fine-tune on your brand voice once. No per-word charges ever.
AI Models You Can Actually Run
| Model | Parameters | Quantization | VRAM Needed | Fits on GTR9? |
|——-|————|————–|————-|—————|
| Llama 3.1 8B | 8B | 4-bit (Q4_K_M) | ~5 GB | ✅ Easy |
| Llama 3.1 70B | 70B | 4-bit (Q4_K_M) | ~40 GB | ✅ Comfortable |
| Llama 3.1 405B | 405B | 4-bit (Q4_K_M) | ~230 GB | ❌ Single unit |
| Qwen 2.5 72B | 72B | 4-bit | ~42 GB | ✅ Comfortable |
| DeepSeek Coder 33B | 33B | 4-bit | ~20 GB | ✅ Easy |
| Nemotron 3 Ultra | 53B | 4-bit | ~32 GB | ✅ Comfortable |
| Phi-3.5 Mini | 3.8B | 4-bit | ~2.5 GB | ✅ Trivial |
Real talk: With 128GB unified memory, you’re not just running one model. You’re running Llama 3 70B for reasoning, DeepSeek Coder for code, and a reranker for RAG — all loaded simultaneously. Switch between them instantly.
Cost vs. Cloud: The Math That Matters
### Cloud API (GPT-4o, 1M tokens/day)
– Input: $2.50/M tokens × 30 days = $75/month
– Output: $10/M tokens × 30 days = $300/month
– Annual: $4,500/year (and rising)
### Beelink GTR9 Pro 395
– Hardware: $4,349 (one-time)
– Electricity: ~45W idle, ~120W full load = ~$15/month
– Year 1: $4,529 | Year 2+: $180/year
Break-even: Month 11. After that, it’s pure savings. And you own the hardware — resell it, repurpose it, cluster it.
The Catch (Because There’s Always One)
It’s not a magic wand.
– No CUDA. AMD ROCm works for PyTorch, but some libraries still assume NVIDIA. llama.cpp, vLLM, and Ollama run beautifully. TensorRT-LLM? No.
– Single-channel memory bandwidth. 8000 MHz LPDDR5X sounds fast, but it’s 128-bit bus. Expect 15-25 tokens/sec on 70B models. Fast enough for interactive use. Not for batch processing thousands of documents.
– No ECC memory. For a law firm or medical office, this matters. Bit flips are rare but real.
– Thermal throttling under sustained load. The fan spins up. It’s audible. Not server-room loud, but noticeable in a quiet office.
– No redundant power supply. If this runs mission-critical inference, get a UPS.
Who Should Buy This
✅ Buy if:
– You need data privacy (legal, medical, finance, defense)
– You spend >$300/month on AI APIs
– You want to experiment with open models without meter running
– You have technical staff who can manage Ollama / llama.cpp / vLLM
– You value owning your compute
❌ Skip if:
– You need CUDA-only tooling (TensorRT, some fine-tuning frameworks)
– You need >100 tokens/sec sustained throughput
– You want plug-and-play managed service
– Your workload justifies a real server with ECC RAM and redundant PSUs
Verdict
The Beelink GTR9 Pro 395 is the first mini PC that makes “local AI for business” a realistic option, not a hobbyist experiment. 128GB unified memory changes the equation entirely — you’re not picking which model fits; you’re loading the models you need and switching between them.
At $4,349, it pays for itself in under a year versus cloud APIs. After that, every inference is essentially free.
For a small business serious about AI adoption without surrendering data or budget, this is the smartest hardware purchase you’ll make in 2024.
Next Steps
– See specs & pricing: [Beelink GTR9 Pro 395 on Global AI Workforce](https://devices.globalaiworkforce.com/product/beelink-gtr9-pro-395-mini-pc-ryzen-ai-max-395126tops16c-32t5-1ghz-128g-lpddr5x-2tb-pcie4-0-x4-ssd-mini-computer-amd-radeon-8060s-built-in-mic-usb4-wifi7-bt5-4-dual-10gbps/)
– Read next: “GMKtec EVO-X2: Same Chip, Different Mission — Gaming Meets AI Workstation”
– Weekly guide: “Run Llama 3.1 70B on the GTR9: Step-by-Step with Ollama”